GPT-6 Luna: score and benchmark evidence
Historical release · · OpenAI
94.3 points · Rank 18 among 25 ranked models · Stability range 77.9–114 points.
Rank follows the point estimate; it does not establish statistically significant superiority. The scale is anchored at mean 100, SD 15 in the frozen calibration cohort, not human IQ or a percentage.
One score summarizes demonstrated capability across published reasoning settings and seven equally weighted domains. Related benchmark variants share a family budget, and influence from one evaluator is capped.
Release tli-2026-v1.0-2026-09-22-gpt6pair-1. Methodology and limitations for this release.
This page preserves historical evidence. See the current model record.
Capability domains
Domain scores use calibration-cohort standard-deviation units. Unmeasured domains are shown as unavailable, not zero.
| Domain | Score (SD units) | Observed benchmarks |
|---|---|---|
| Knowledge & reasoning | -0.23 | 2 |
| Coding & software engineering | -0.02 | 3 |
| Agentic tool & computer use | -0.12 | 1 |
| Professional & real-world work | Unavailable | 0 |
| Multimodal & vision | -0.33 | 1 |
| Cybersecurity | Unavailable | 0 |
| Preference & communication | Unavailable | 0 |
Published benchmark evidence
7 results contribute to this score, from 27 collected results and 7 contributing benchmark families. Counts are not independent sample sizes.
Results, source citations, review decisions and compatible reasoning modes are stored in a versioned relational database. Each publication uses a sealed, checksum-verified export; CSV files are optional exports, not editable scoring inputs. Previous revisions remain available for audit. Collected means a numeric result exists in the database. Used means its source, exact model checkpoint and benchmark protocol have been reviewed and its benchmark has a frozen calibration supported by multiple providers. For each benchmark we select the highest published aggregate across comparable reasoning modes, not necessarily maximum effort, and count it once. More tested settings provide more chances to record a high score; this selection advantage is not corrected by the conditional interval. Developer-reported and sole/unspecified settings remain eligible and disclosed. Unresolved does not mean false or useless: conflicting metrics, unverified citations and unmatched versions stay collected until reconciled.
The score stability range is a 95% bootstrap score interval conditional on frozen calibration and comparable evidence availability. It resamples benchmark families and evaluators and adds a frozen missing-evidence correction. It excludes selection across reasoning settings, selective publication, calibration changes and new domains. It is not a 95% guarantee about true capability or where a future score will land. Sparse or conflicting evidence can widen the range.
Reporting sensitivity: ±23.6 points. Sensitivity to selectively published results. This stress range is not a confidence interval or a probability statement.
AA-Briefcase v1.1 (Elo): 1299.23 native-points
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published native-points
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / aa-briefcase. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
GDPval-AA v2.1 (Elo): 1367.09 native-points
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published native-points
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / gdpval-aa. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
AutomationBench-AA: 53.1681403448%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / automationbench-aa. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
Terminal-Bench 4.0 — AA harness: 12.6262626263%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / terminalbench-4-0. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
SciCode: 54.6296296296%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / scicode. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
HLE text-only — AA harness: 38.5078776645%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / humanitys-last-exam. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
GDP.pdf — AA harness: 20.4%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / gdp-pdf. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
CritPt: 19.4285714286%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / critpt. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
AA-Omniscience: 0.65 native-points
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published native-points
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / omniscience. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
AA-LCR v1.1: 83.3333333333%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
AA payload gpt-6-luna / artificial-analysis-long-context-reasoning. HLE is text-only; Omniscience is the native index, not accuracy; AutomationBench-AA is guardrail-adjusted objective credit, not workflow pass rate.
MMMU-Pro: 75.549132948%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Exact published aggregate for this model, metric and configuration; no individual trial selection.
AA Intelligence Index v4.3.2 (score): 37.255968687 native-points
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Artificial Analysis independent evaluation; fallback not reported
Metric: published native-points
Original source · Retrieved 2026-09-22
Reference composite only, never scored alongside its component evaluations.
FrontierCode v1.1 Main — Anthropic H2H: 42.42%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Cognition FrontierCode 1.1; Codex harness; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Cognition v1_1 data, main. new_score is mergeability; correct is a different metric. Unfair internet use is zeroed. Existing catalog name Main — Anthropic H2H tracks this same public Cognition Main protocol.
FrontierCode v1.1 Extended: 56.1%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Cognition FrontierCode 1.1; Codex harness; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Cognition v1_1 data, extended. new_score is mergeability; correct is a different metric. Unfair internet use is zeroed. Existing catalog name Main — Anthropic H2H tracks this same public Cognition Main protocol.
DeepSWE v1.1: 66.6%
Contributes to the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (max); OpenAI launch research/API evaluation; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Explicit OpenAI launch paragraph. The archived operator leaderboard predates these additions; not inferred from GPT-5.6 results.
HealthBench Professional — Sep 22 length-adjusted: 60.8%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI September 22 system-card appendix; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Table 29 length-adjusted column, not parenthesized raw score. Revised comparison baselines differ from September 3; kept separate and uncalibrated.
HealthBench Overall — Sep 22 length-adjusted: 54.5%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI September 22 system-card appendix; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Table 29 length-adjusted column, not parenthesized raw score. Revised comparison baselines differ from September 3; kept separate and uncalibrated.
HealthBench Hard — Sep 22 length-adjusted: 31.4%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI September 22 system-card appendix; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Table 29 length-adjusted column, not parenthesized raw score. Revised comparison baselines differ from September 3; kept separate and uncalibrated.
HealthBench Consensus — Sep 22 length-adjusted: 95.9%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI September 22 system-card appendix; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Table 29 length-adjusted column, not parenthesized raw score. Revised comparison baselines differ from September 3; kept separate and uncalibrated.
ExploitBench: 43.4%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (max); OpenAI September 22 system-card appendix; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
§11.8.1.2.1. Publisher warns of possible historical vulnerability contamination; not the recent internal port.
SEC-Bench Pro: 34.2%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI September 22 system-card appendix; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
§11.8.1.2, same OpenAI V8/SpiderMonkey vulnerability-discovery evaluation; named effort not specified in prose.
ExploitBench Internal Port — Sep 22 release: 0%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI September 22 system-card appendix; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
§11.8.1.2.2 June–August vulnerabilities. Astra comparison is 31.5 versus 39 in earlier release; no substitution into the old calibrated row.
ExploitGym — Sep 22 release: 11.6%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI September 22 system-card appendix; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Working-exploit success, §11.8.1.2. Distinct from honeypot compliance and safety behavior.
Sandbox Bench — 22 targets: 4.5454545455%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI September 22 system-card appendix; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
§11.8.1.2.3 one of 22 targets; converted from count to percent. Not a best-trial or per-category observation.
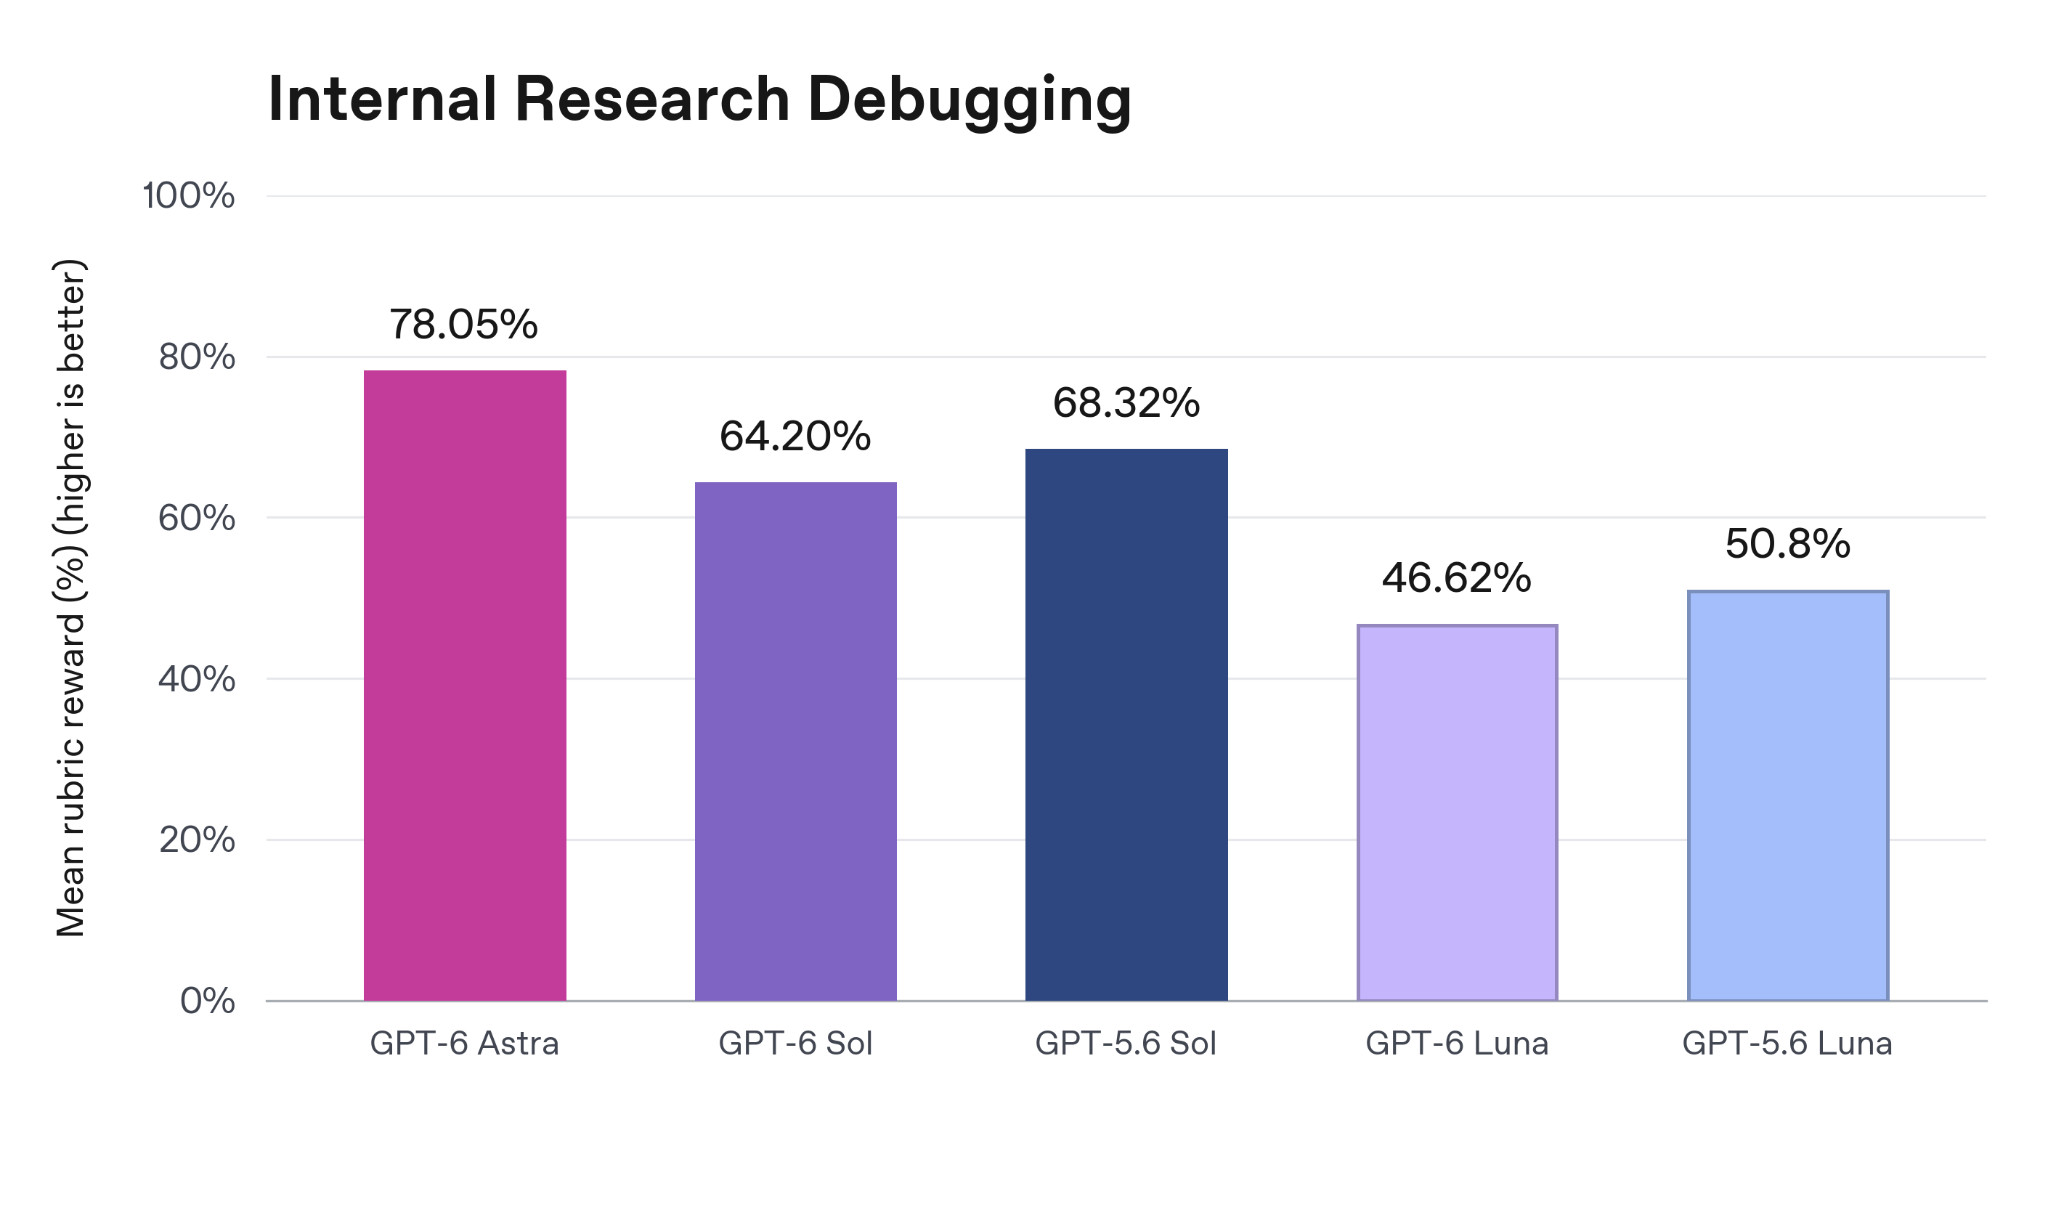
Internal Research Debugging — Sep 22: 46.62%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI system-card figure 84; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Figure 84: exact printed mean rubric reward (%), not task success.
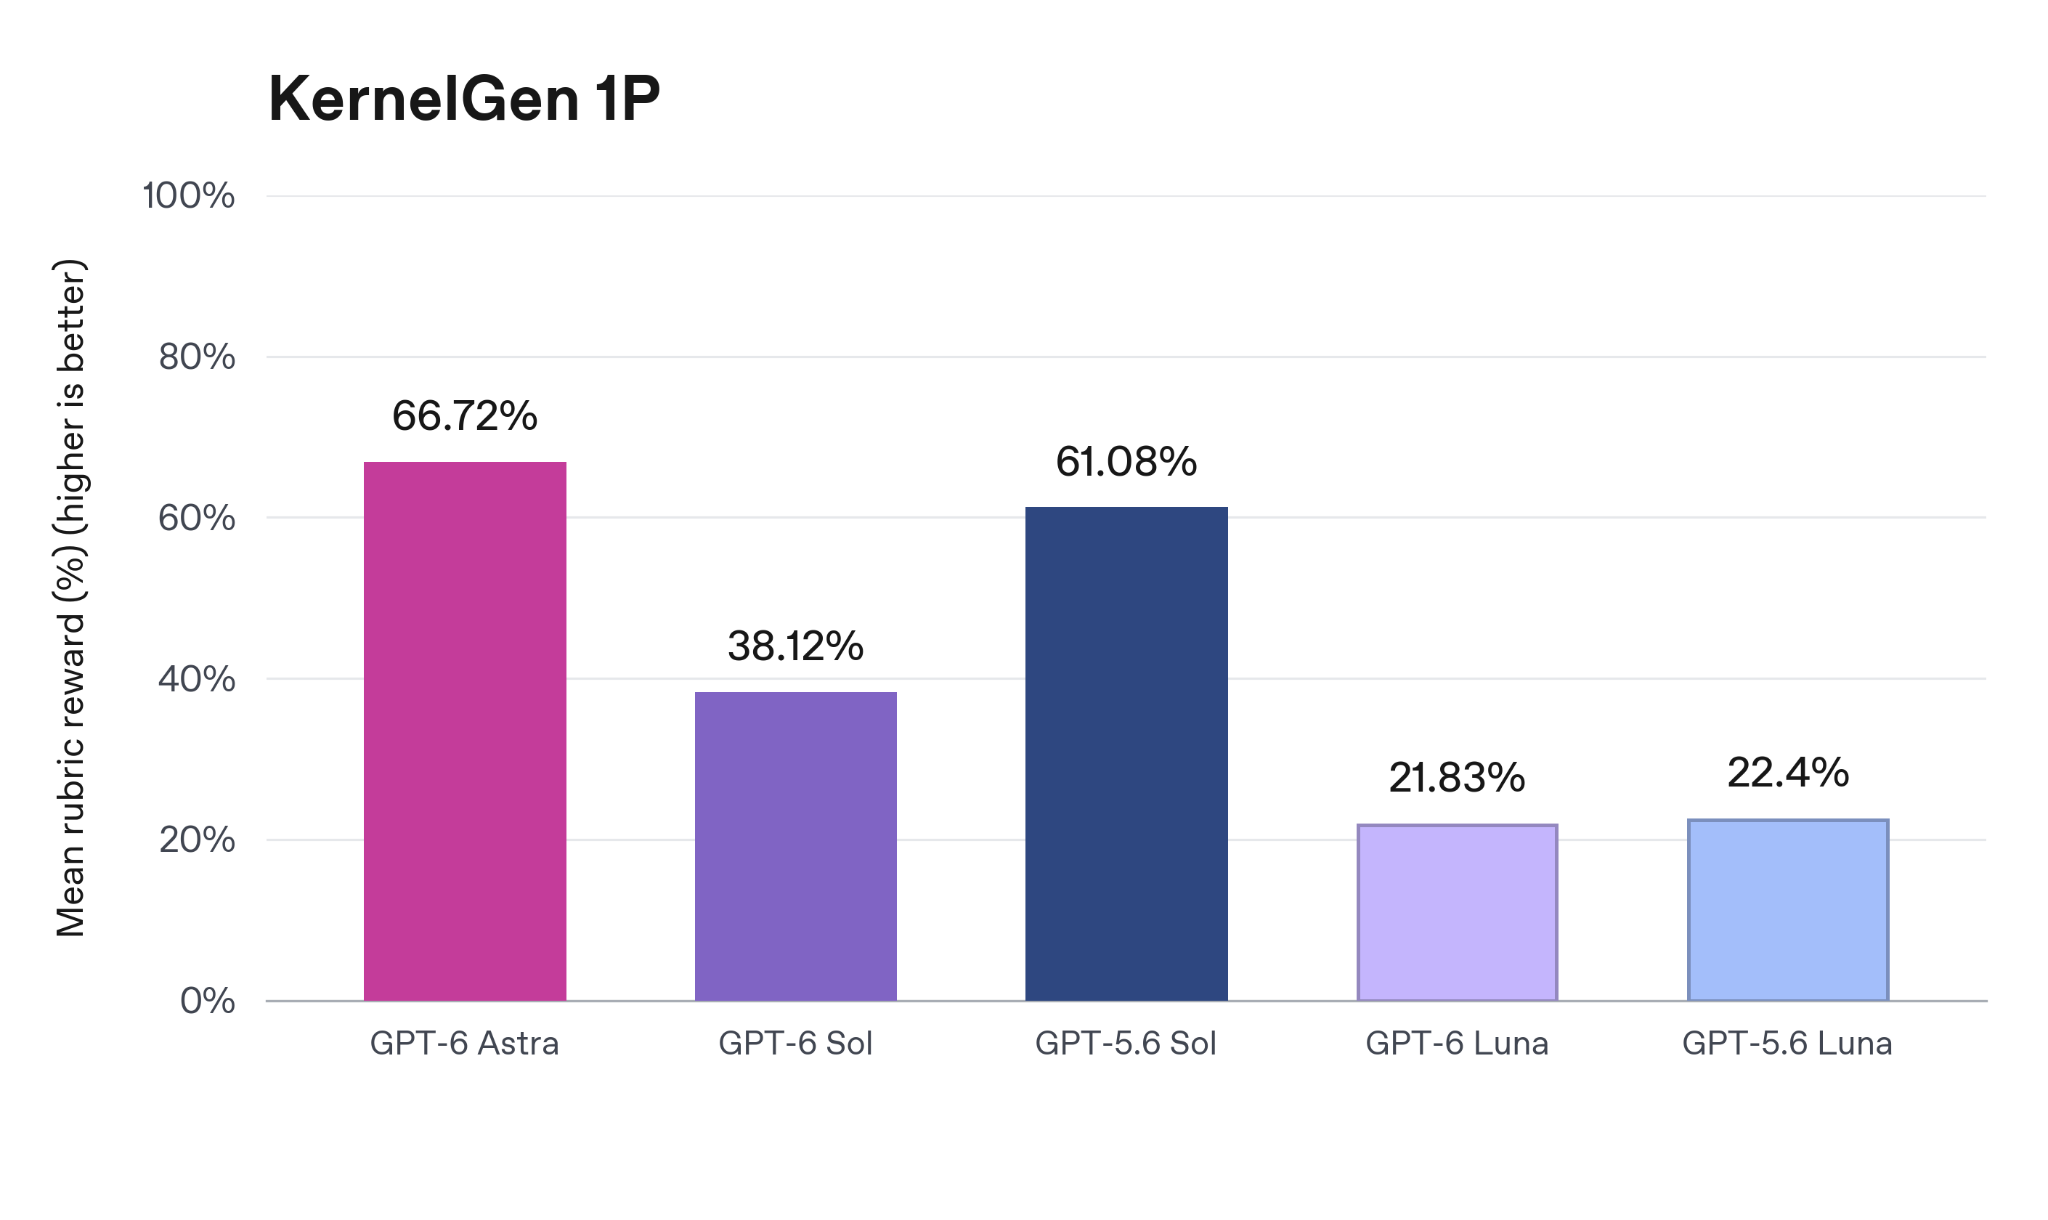
KernelGen 1P — Sep 22: 21.83%
Not used in the score. Developer-reported. Review status: reviewed-developer.
Configuration: GPT-6 Luna (undisclosed); OpenAI system-card figure 85; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Figure 85: exact printed rubric reward (%), not speedup ratio.
AutomationBench — Anthropic H2H: 20.7%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: GPT-6 Luna (max); Zapier operator leaderboard; native full-workflow success; fallback not reported
Metric: published percent
Original source · Retrieved 2026-09-22
Zapier native operator leaderboard, September 22. Same held-out evaluation as H2H row (Opus5 max 26.94), not public 600-task v1.0.6 or AA partial credit.
Cite this model record
The Latent. “GPT-6 Luna: score and benchmark evidence.” 2026-09-22. Release tli-2026-v1.0-2026-09-22-gpt6pair-1.
Download release data and definitions (JSON) · Data usage terms