Muse Spark Open: score and benchmark evidence
Historical release · · Meta
96.7 points · Rank 24 among 34 ranked models · Stability range 79.3–113.7 points.
Rank follows the point estimate; it does not establish statistically significant superiority. The scale is anchored at mean 100, SD 15 in the frozen calibration cohort, not human IQ or a percentage.
One score summarizes demonstrated capability across published reasoning settings and seven equally weighted domains. Related benchmark variants share a family budget, and influence from one evaluator is capped.
Release tli-2026-v1.0-2026-10-19-refresh-31. Methodology and limitations for this release.
This page preserves historical evidence. See the current model record.
Capability domains
Domain scores use calibration-cohort standard-deviation units. Unmeasured domains are shown as unavailable, not zero.
| Domain | Score (SD units) | Observed benchmarks |
|---|---|---|
| Knowledge & reasoning | -0.03 | 2 |
| Coding & software engineering | -0.18 | 3 |
| Agentic tool & computer use | Unavailable | 0 |
| Professional & real-world work | 0.05 | 5 |
| Multimodal & vision | -0.25 | 2 |
| Cybersecurity | Unavailable | 0 |
| Preference & communication | Unavailable | 0 |
Published benchmark evidence
12 results contribute to this score, from 20 collected results and 12 contributing benchmark families. Counts are not independent sample sizes.
Results, source citations, review decisions and compatible reasoning modes are stored in a versioned relational database. Each publication uses a sealed, checksum-verified export; CSV files are optional exports, not editable scoring inputs. Previous revisions remain available for audit. Collected means a numeric result exists in the database. Used means its source, exact model checkpoint and benchmark protocol have been reviewed and its benchmark has a frozen calibration supported by multiple providers. For each benchmark we select the highest published aggregate across comparable reasoning modes, not necessarily maximum effort, and count it once. More tested settings provide more chances to record a high score; this selection advantage is not corrected by the conditional interval. Developer-reported and sole/unspecified settings remain eligible and disclosed. Unresolved does not mean false or useless: conflicting metrics, unverified citations and unmatched versions stay collected until reconciled.
The score stability range is a 95% bootstrap score interval conditional on frozen calibration and comparable evidence availability. It resamples benchmark families and evaluators and adds a frozen missing-evidence correction. It excludes selection across reasoning settings, selective publication, calibration changes and new domains. It is not a 95% guarantee about true capability or where a future score will land. Sparse or conflicting evidence can widen the range.
Reporting sensitivity: ±19.0 points. Sensitivity to selectively published results. This stress range is not a confidence interval or a probability statement.
AA-Briefcase v1.1 (Elo): 1279.25 native-points
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-16; fallback not reported
Metric: published native-points
Original source · Retrieved 2026-10-16
Daily evaluator refresh; replaces 1280.13 recorded 2026-10-15.
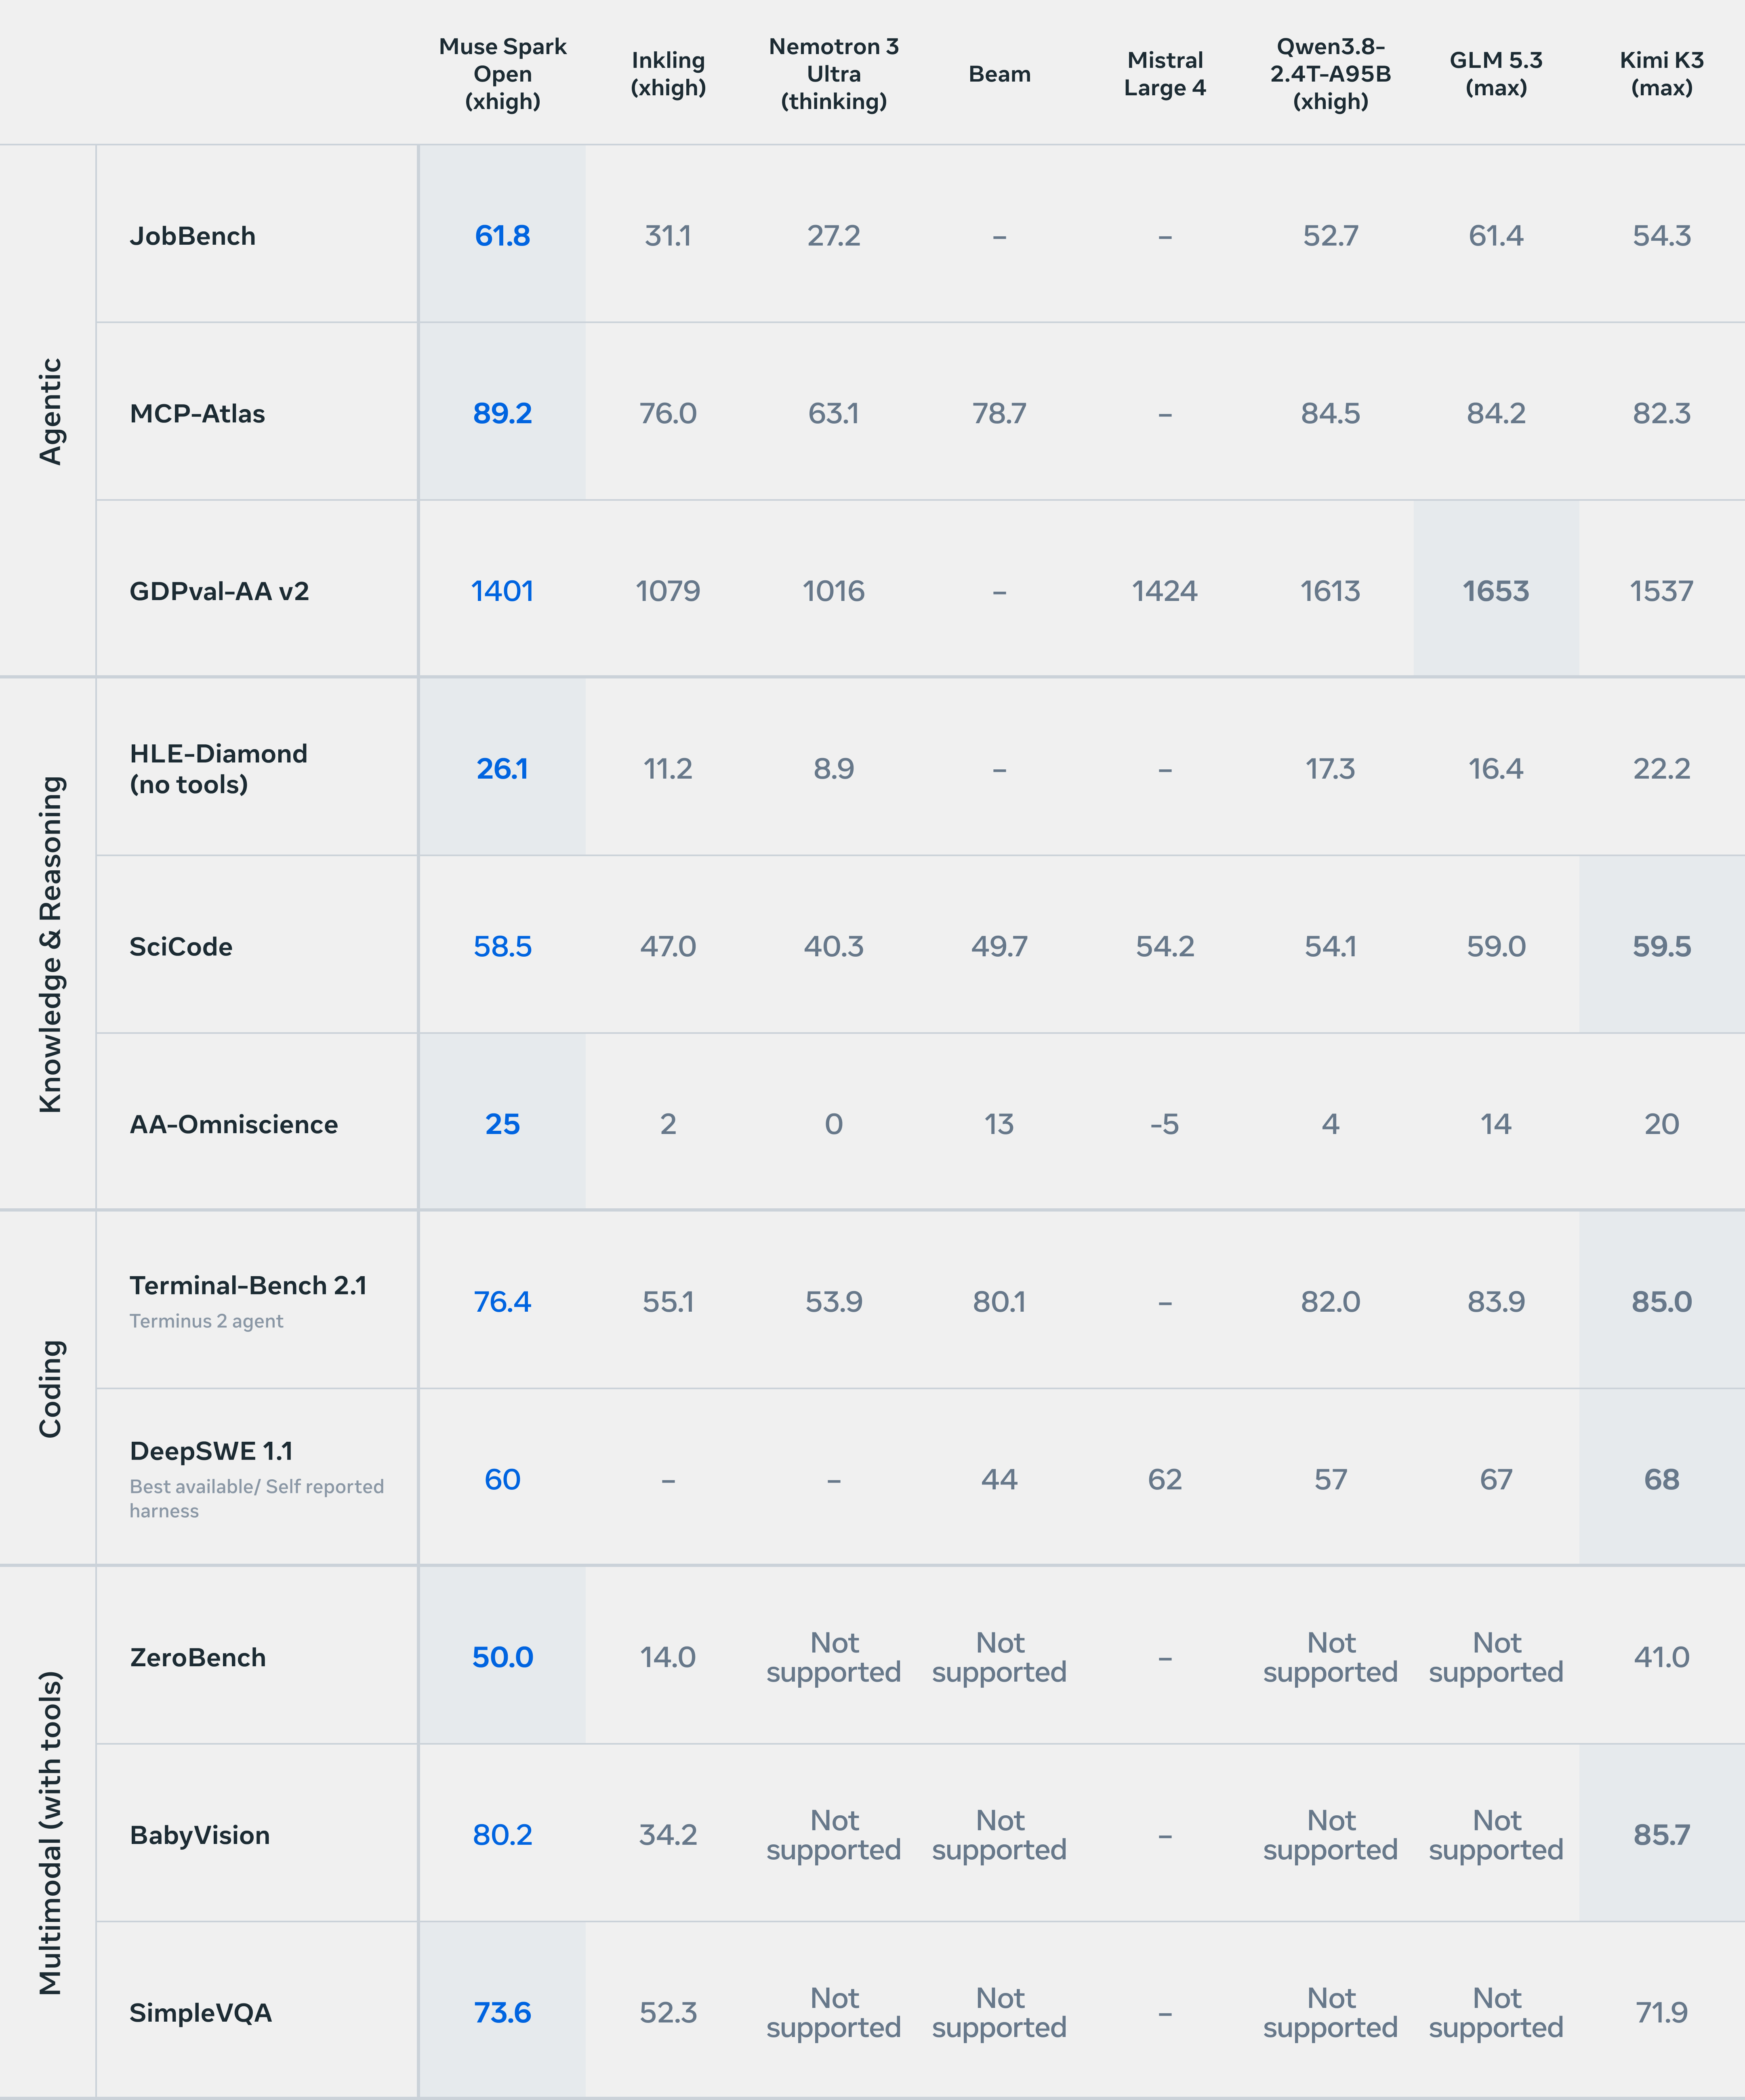
GDPval-AA v2.1 (Elo): 1401.12 native-points
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published native-points
Original source · Retrieved 2026-10-15
Exact model and effort in the evaluator chart payload.
AutomationBench-AA: 49.7081182731%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Exact model and effort in the evaluator chart payload.
Terminal-Bench 4.0 — AA harness: 8.0808080808%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Exact model and effort in the evaluator chart payload.
SciCode: 58.4490740741%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Exact model and effort in the evaluator chart payload.
HLE text-only — AA harness: 43.8832252085%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Exact model and effort in the evaluator chart payload.
GDP.pdf — AA harness: 18.6%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Exact model and effort in the evaluator chart payload.
CritPt: 14.8571428571%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Exact model and effort in the evaluator chart payload.
AA-Omniscience: 24.65 native-points
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published native-points
Original source · Retrieved 2026-10-15
Exact model and effort in the evaluator chart payload.
AA-LCR v1.1: 78.3333333333%
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Exact model and effort in the evaluator chart payload.
MMMU-Pro: 80.9248554913%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Independent MMMU-Pro aggregate for this effort.
AA Intelligence Index v4.3.2 (score): 38.8666662998 native-points
Not used in the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Artificial Analysis independent evaluation, 2026-10-15; fallback not reported
Metric: published native-points
Original source · Retrieved 2026-10-15
Reference composite only, never scored alongside its component evaluations.
JobBench: 61.8%
Contributes to the score. Developer-reported. Review status: reviewed-developer.
Configuration: Muse Spark Open (xhigh); Muse Spark Open developer-reported result (meta); fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Developer-reported result entered in the newsroom. Same protocol as the catalogue row: the lab table reproduces cells we hold (kimi-k3 54.3). Value read from an image of the lab table.
BabyVision (with CI): 80.2%
Contributes to the score. Developer-reported. Review status: reviewed-developer.
Configuration: Muse Spark Open (xhigh); Muse Spark Open developer-reported result (meta); fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-15
Developer-reported result entered in the newsroom. Same protocol as the catalogue row: the lab table reproduces cells we hold (kimi-k3 85.7). Value read from an image of the lab table.
Code Migration †: 21.17%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Vals AI Code Migration harness; provider Together AI; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-17
Vals AI model page, headline accuracy 21.17 ± 3.47, rank 51/78. Vals notes some benchmarks may use a different provider or parameters.
Excel Modeling Benchmark — Vals: 53.67%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Vals AI EMB harness; provider Together AI; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-17
Vals AI model page, headline accuracy 53.67 ± 3.2, rank 50/75. Vals notes some benchmarks may use a different provider or parameters.
Finance Agent v2 — Vals: 61.34%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Vals AI Finance Agent (v2) harness; provider Together AI; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-17
Vals AI model page, headline accuracy 61.34 ± 2.09, rank 3/79. Vals notes some benchmarks may use a different provider or parameters.
Harvey LAB (Vals): 16.67%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Vals AI Harvey's Legal Agent Benchmark harness; provider Together AI; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-17
Vals AI model page, headline accuracy 16.67 ± 3.09, rank 9/80. Vals notes some benchmarks may use a different provider or parameters.
Legal Research Bench — Vals: 38.46%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Vals AI Legal Research Bench harness; provider Together AI; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-17
Vals AI model page, headline accuracy 38.46 ± 3.38, rank 35/79. Vals notes some benchmarks may use a different provider or parameters.
Vibe Code Bench v1.1 — Vals: 76.19%
Contributes to the score. Source category: independent. Review status: reviewed-independent.
Configuration: Muse Spark Open (xhigh); Vals AI Vibe Code Bench v1.1 harness; provider Together AI; fallback not reported
Metric: published percent
Original source · Retrieved 2026-10-17
Vals AI model page, headline accuracy 76.19 ± 3.32, rank 34/113. Vals notes some benchmarks may use a different provider or parameters.
Cite this model record
The Latent. “Muse Spark Open: score and benchmark evidence.” 2026-10-19. Release tli-2026-v1.0-2026-10-19-refresh-31.
Download release data and definitions (JSON) · Data usage terms